Reinforcement Learning: Principles and Use Cases
Reinforcement learning (RL) is a paradigm in machine learning where an agent learns to make decisions by interacting with an environment to maximize a cumulative reward signal. Unlike supervised learning, which relies on labeled examples, RL focuses on learning from trial and error, making it suitable for sequential decision-making problems. This article explores the core principles of RL, including reward systems, agents, and environments, and discusses practical use cases in robotics, gaming, and dynamic pricing.
The fundamental idea behind RL is that an agent takes actions in an environment, receives feedback in the form of rewards, and adjusts its behavior to achieve a goal. This iterative process allows the agent to discover optimal strategies over time, balancing exploration of new actions with exploitation of known ones. RL has gained significant attention due to its success in complex domains, from mastering board games to controlling robots.
In this article, we will delve into the key components of RL, examine algorithms and challenges, and highlight real-world applications. Whether you are new to the field or seeking to deepen your understanding, this overview provides a structured perspective on how RL systems operate and where they are applied.
Core Components of Reinforcement Learning
At its heart, reinforcement learning involves four main elements: the agent, the environment, actions, and rewards. The agent is the decision-maker, which could be a software program, a robot, or any entity capable of taking actions. The environment is everything external to the agent with which it interacts. At each step, the agent observes the current state of the environment, selects an action, and receives a reward signal indicating the immediate desirability of that action. The environment then transitions to a new state, and the cycle repeats.
The goal of the agent is to learn a policy—a mapping from states to actions—that maximizes the expected cumulative reward over time. This is often formalized using the concept of return, which is the sum of discounted future rewards. The discount factor determines how much the agent values immediate rewards versus long-term rewards. A high discount factor emphasizes future rewards, while a low one prioritizes immediate gains.
Another crucial concept is the value function, which estimates how good it is for the agent to be in a given state or to take a specific action in that state. The action-value function, or Q-function, quantifies the expected return when taking an action in a state and then following a certain policy. These functions are central to many RL algorithms, as they guide the agent’s decision-making.
Learning in RL typically involves balancing exploration and exploitation. Exploration allows the agent to discover new strategies that might yield higher rewards, while exploitation leverages known actions that already produce good results. Striking the right balance is essential, as too much exploration can lead to inefficiency, while too much exploitation can cause the agent to miss better opportunities. Various strategies, such as epsilon-greedy or softmax, are used to manage this trade-off.
Algorithms and Methodologies
Reinforcement learning algorithms can be broadly categorized into value-based, policy-based, and actor-critic methods. Value-based algorithms, such as Q-learning and its deep learning variant DQN, focus on learning the optimal action-value function. From this function, the optimal policy is derived by selecting the action with the highest value in each state. These methods are often effective in discrete action spaces but can struggle with continuous actions.
Policy-based methods, like REINFORCE and Proximal Policy Optimization (PPO), directly learn a policy without explicitly modeling value functions. They are well-suited for continuous action spaces and can handle stochastic policies naturally. However, they may suffer from high variance in gradient estimates, requiring techniques like baseline subtraction to stabilize learning.
Actor-critic methods combine the strengths of both approaches. They maintain two components: an actor that updates the policy and a critic that evaluates the policy by estimating value functions. This hybrid approach often leads to more stable and efficient learning. Popular actor-critic algorithms include A3C, A2C, and Soft Actor-Critic (SAC).
Model-based RL takes a different route by learning a model of the environment’s dynamics and using it for planning. This can significantly improve sample efficiency, as the agent can simulate experiences without interacting with the real environment. However, learning an accurate model can be challenging, especially in complex, high-dimensional environments. Model-free methods, in contrast, learn directly from experience without an explicit model and are often simpler to implement but may require more data.
Regardless of the specific algorithm, challenges such as sparse rewards, large state spaces, and non-stationary environments persist. Techniques like reward shaping, hierarchical RL, and transfer learning are active areas of research aimed at addressing these issues. The choice of algorithm depends on the problem characteristics, including the nature of the state and action spaces, the availability of a simulator, and computational resources.
Use Cases in Robotics and Gaming
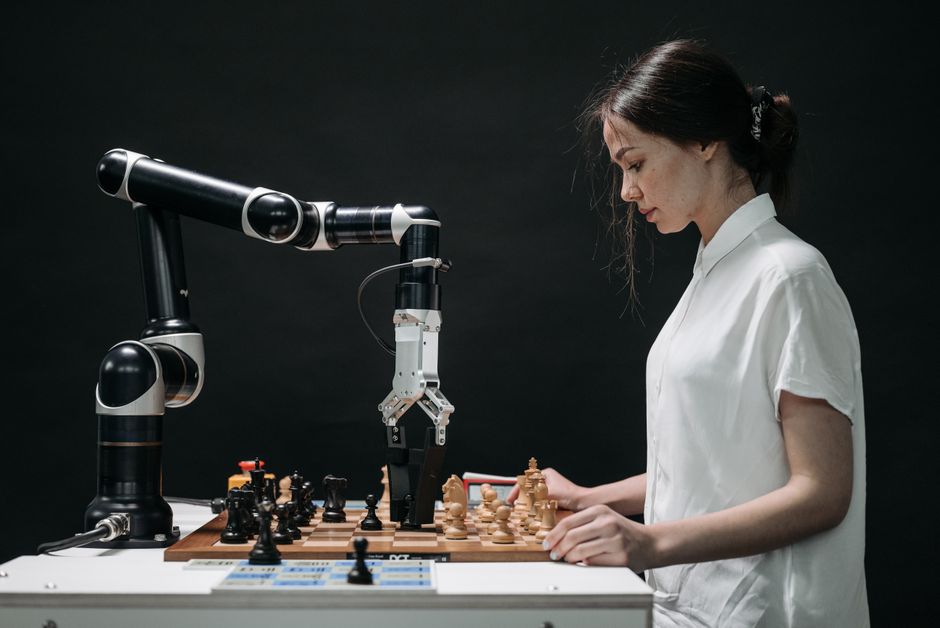
Reinforcement learning has demonstrated remarkable success in robotics, where it enables robots to acquire complex motor skills through trial and error. For instance, RL has been used to teach robotic arms to grasp objects, legged robots to walk on uneven terrain, and drones to perform acrobatic maneuvers. In these scenarios, the reward function often combines task-specific objectives with penalties for unsafe or inefficient behavior. Simulations are frequently employed to train policies before deploying them on physical robots, reducing wear and tear and accelerating learning.
In gaming, RL has achieved superhuman performance in games like Go, Chess, and various video games. AlphaGo, developed by DeepMind, famously defeated world champions using a combination of deep learning and Monte Carlo tree search. More recently, agents have learned to play Atari games from raw pixels using deep Q-networks, and complex real-time strategy games like Dota 2 and StarCraft II have been tackled with multi-agent RL techniques. These successes highlight RL’s ability to handle high-dimensional observations and long-term planning.
The gaming domain also serves as a benchmark for RL research, providing diverse challenges such as partial observability, delayed rewards, and large action spaces. Many algorithmic innovations, including experience replay and prioritized replay, were first validated in games. Moreover, gaming environments offer a safe and reproducible setting for testing new ideas before applying them to real-world problems.
Beyond entertainment, the principles learned from gaming have influenced other areas, such as autonomous driving and healthcare. For example, RL can be used to optimize treatment policies for chronic diseases, where the state includes patient vitals and the actions are medication dosages. However, such applications require careful consideration of safety and ethical constraints, as the consequences of errors can be severe.
Dynamic Pricing and Business Applications
Dynamic pricing is a business strategy where prices for products or services are adjusted over time based on demand, supply, and other factors. Reinforcement learning offers a principled approach to learn optimal pricing policies by modeling the problem as an RL task. The agent (pricing algorithm) observes market conditions (state), sets prices (actions), and receives rewards in the form of revenue or profit. The environment includes customer behavior, competitor actions, and inventory levels.
One advantage of RL in dynamic pricing is its ability to adapt to changing market dynamics without relying on predefined rules. For instance, in e-commerce, an RL agent can learn to adjust prices in real time to maximize long-term revenue while maintaining customer satisfaction. It can also handle trade-offs between short-term gains and long-term customer loyalty. Simulations and A/B testing are often used to evaluate pricing policies before full deployment.
Other business applications of RL include supply chain management, where agents optimize inventory replenishment and logistics; personalized recommendations, where the agent selects items to present to users to maximize engagement; and energy management, where agents control heating, ventilation, and air conditioning systems to reduce consumption. In finance, RL has been explored for portfolio management and algorithmic trading, though these domains pose additional challenges due to non-stationarity and risk considerations.
When implementing RL for business problems, it is crucial to define appropriate reward functions that align with organizational objectives and constraints. For example, a reward function that solely maximizes revenue might lead to customer churn, so it may be combined with metrics like customer lifetime value. Additionally, deploying RL in production requires robust evaluation, monitoring, and fallback mechanisms to handle unexpected situations. Companies like NeuralArc provide tools and expertise to help organizations navigate these complexities and build effective RL solutions.
Challenges and Future Directions
Despite its successes, reinforcement learning faces several challenges that limit its widespread adoption. Sample inefficiency is a major hurdle: many algorithms require millions of interactions to learn effective policies, which can be impractical in real-world settings. Researchers are addressing this through techniques like meta-learning, which enables agents to learn new tasks quickly by leveraging prior experience, and imitation learning, where agents learn from demonstrations.
Another challenge is the design of reward functions. Specifying a reward that accurately captures the desired behavior is often difficult, and poorly designed rewards can lead to unintended consequences, a phenomenon known as reward hacking. For example, an agent might find a loophole to maximize reward without achieving the intended goal. Inverse reinforcement learning aims to infer reward functions from expert demonstrations, while reward shaping incorporates domain knowledge to guide learning.
Safety and reliability are critical concerns, especially in applications like autonomous driving and healthcare. Ensuring that RL agents behave safely in all situations is an active research area, with approaches such as constrained RL and safe exploration. Interpretability of learned policies is also important for building trust and for regulatory compliance.
Looking ahead, the integration of RL with other AI techniques, such as deep learning and probabilistic modeling, is expected to drive further advances. Multi-agent RL, where multiple agents interact and learn simultaneously, is relevant for modeling complex systems like traffic and markets. Additionally, advances in computational hardware and simulation environments will continue to enable more sophisticated applications. As the field matures, we can expect to see RL deployed in increasingly diverse domains, from personalized medicine to smart cities.
In conclusion, reinforcement learning provides a powerful framework for sequential decision-making under uncertainty. By understanding its core principles and being aware of its challenges, practitioners can leverage RL to create innovative solutions. Whether in robotics, gaming, dynamic pricing, or beyond, RL continues to push the boundaries of what is possible with artificial intelligence.